blog
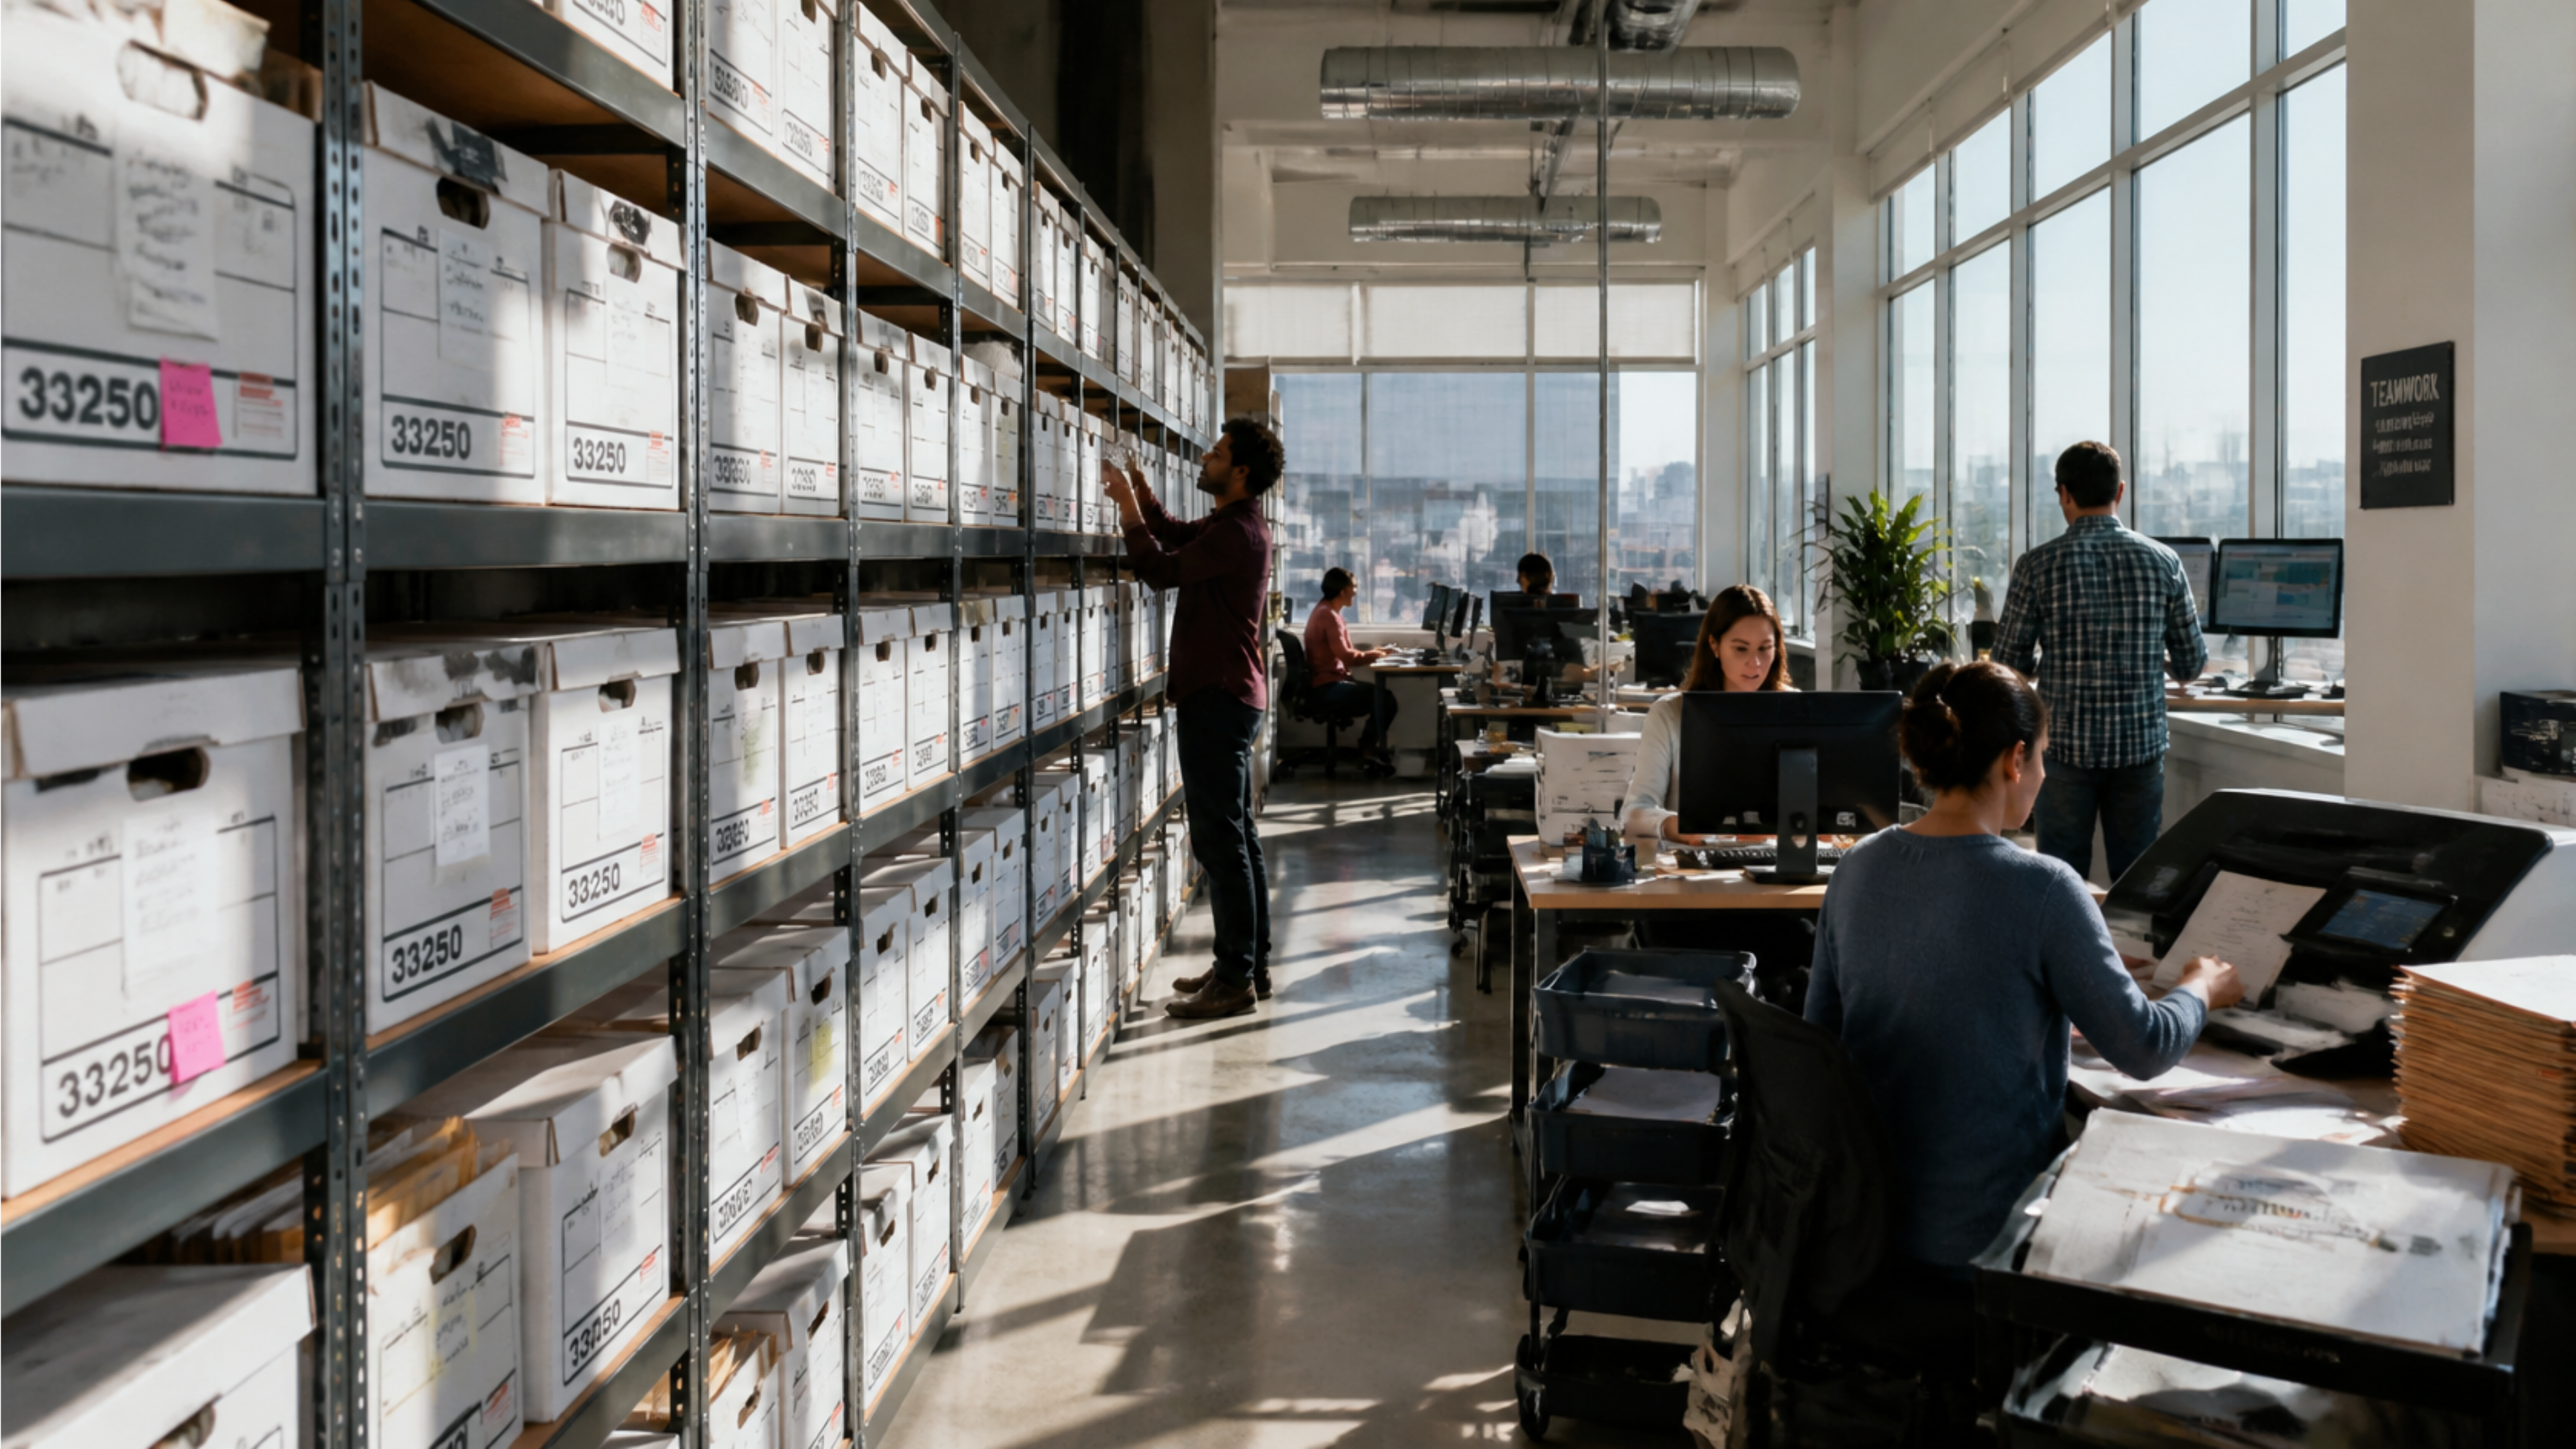
Organizations don't usually decide to digitize millions of documents overnight. More often, it's the result of years of accumulated paper records, growing storage costs, inefficient workflows, and employees spending too much time looking for information that should be readily available.
Eventually, something has to change.
But moving from physical records to digital information involves a lot more than finding a scanning vendor and sending over a few pallets of boxes.
A successful large-scale document digitization project requires decisions about what to digitize, how to prepare documents, what information to capture, how to maintain quality, and where everything will go once the work is complete.
Those decisions matter. Without a plan, organizations can spend significant time and money converting physical records into digital files that are still difficult to search, organize, and use.
Whether you're digitizing a few hundred thousand pages or an archive containing millions of documents, here's what to consider before getting started.
1. Understand What You Have Before You Start
You can't digitize what you don't understand. The first step in any large-scale records digitization project is understanding the records themselves.
Before establishing a digitization timeline or budget, take inventory of what you're working with.
That means looking beyond a simple page count. Start by understanding:
- Volume: How many boxes, folders, files, and individual pages need to be processed?
- Location: Where are the records currently stored? Are they spread across multiple places like a third-party storage facility, active departmental cabinets, or a basement archive?
- Organization: How are the records currently arranged? By department, date, customer, case number, or another filing system?
- Document types: What kinds of records are included? Contracts, invoices, personnel files, engineering drawings, case files, or something else?
- Condition: What condition are the documents in? Are they in good shape, or do they include fragile paper, water damage, faded text, heavy bindings, or damaged pages?
- Duplicates: Are there multiple copies of the same records?
- Formats: Are you working exclusively with paper, or do you also have microfilm, microfiche, oversized documents, or other media?
A records inventory gives you the baseline for everything that comes next; it provides the information needed to estimate project scope, identify potential challenges, and determine the right approach to processing.
It can also reveal opportunities to simplify the project. For example, you may find duplicate records, outdated files, or documents stored in locations that aren't immediately obvious. It also tends to uncover things organizations didn't realize they had before paying to ingest them, saving massive capital down the line.
Maybe records are spread across five facilities instead of one. Maybe an old filing system doesn't match the way the organization actually uses information today. Maybe thousands of documents are duplicates or are already past their retention period.
The earlier you identify those issues, the easier they are to address. You want to discover those things before you start paying to digitize them.
2. Decide What Actually Needs to Be Digitized
Here's a surprisingly important question: Do you need to digitize everything? The short answer is, probably not.
One of the biggest mistakes organizations can make is assuming every physical record needs to be scanned.
In reality, some records may already be eligible for destruction under an approved retention schedule. Others may need to be preserved for legal, regulatory, historical, or operational reasons.
Before digitization begins, review your records retention policies and involve the appropriate records management, legal, and compliance teams. This helps establish which records should be prioritized, which need special handling, and which may no longer need to be retained.
A practical way to approach the decision is to group records by their purpose:
- Active business records: Contracts, invoices, customer files, and other documents employees regularly need to access.
- Regulatory and legal records: Documents subject to retention requirements, audits, litigation holds, or other compliance obligations.
- Historical and archival records: Older documents that need to be preserved but may not be accessed frequently.
- At-risk records: Fragile, aging, or deteriorating documents that could become difficult to recover or read over time.
The right priorities will depend on your organization and industry. For example, a financial institution may prioritize customer account records and loan documentation, while a government agency may focus on public records, permitting files, and historical archives.
The important thing is to establish those priorities before processing begins.
Digitization should make records easier to manage, not create a larger collection of digital files that nobody needs.
3. Prepare Documents for High-Volume Scanning
Physical document preparation is one of the most time-consuming parts of a traditional digitization project.
Paper records weren't designed to move through high-speed scanning equipment. Staples, paper clips, binder clips, rubber bands, folded pages, sticky notes, and damaged documents can all interrupt the process.
Depending on the condition and format of the records, preparation may involve:
- Removing staples and paper clips
- Disassembling binders
- Repairing damaged pages
- Flattening folded documents
- Separating different document types
- Organizing records into batches
- Identifying oversized or fragile materials
- Preparing documents with unusual formats for specialized scanning
For smaller scanning projects, much of this work can be handled manually without creating a major scheduling challenge. This is where manual prep is just a minor annoyance. At enterprise scale, the math changes.
When you're processing millions of pages, even a few seconds of manual handling per document can add up to thousands of hours of manual labor. Manual document preparation is a significant contributor to project cost, turnaround time, and overall production capacity. It’s one area where automation can make a meaningful difference.
At small volumes, these problems are annoying. At millions of pages, they're expensive.
Rather than relying entirely on people to remove fasteners and prepare every page individually, robotic document processing can automate portions of the preparation workflow.
For organizations with substantial physical archives, it's worth understanding how much of the process can be automated before committing to a traditional labor-intensive approach.
4. Decide How Documents Will Be Indexed and Organized
Scanning a document is one thing. Being able to find it six months later is another.
Before production begins, determine how digital records should be organized and what information needs to be captured from each document. This is generally referred to as indexing or metadata extraction.
Depending on the records, relevant information might include:
- Document type
- Customer or vendor name
- Account or contract number
- Case or file number
- Date
- Department or business unit
- Location
- Employee or patient identifier
- Retention category
These fields become the foundation for searching, retrieving, and organizing digital records.
For example, imagine an employee needs to locate a specific contract from 2018. If the document has been scanned but doesn't include the correct contract number, date, or customer information, finding it may still require opening and reviewing multiple files.
Good indexing makes that process much easier.
It's also important to think about where the information will ultimately be used. The metadata requirements for a document management system may differ from those of an ERP, CRM, or enterprise content management platform.
Establishing these requirements upfront helps prevent expensive rework and makes it easier to integrate digitized records into existing business processes.
5. Make Sure Your Digital Documents Are Actually Searchable
A scanned document isn't automatically a searchable digital document.
Without additional processing, a scanned PDF is essentially an image of a page. You can look at it, but a computer can't necessarily recognize or search the text inside it. That's where optical character recognition (OCR) comes in.
OCR technology identifies text within scanned images and converts it into machine-readable information. This makes it possible to search for names, dates, account numbers, and other information contained within documents.
More advanced document processing technologies can go further by identifying document types, extracting specific fields, and organizing information into structured data.
This distinction is increasingly important as organizations look for ways to use their existing information in analytics and AI applications. For example, an organization may want to extract key information from thousands of historical contracts or make decades of archived documents accessible to enterprise search tools. Simply storing those documents as PDFs won't accomplish that. The quality of the underlying data matters.
Older documents, faded text, unusual layouts, handwritten notes, and inconsistent formatting can all affect recognition and extraction accuracy. That's why OCR and intelligent data extraction should be considered part of the overall digitization strategy, not something added as an afterthought.
6. Build Quality Control Into the Workflow
Even with modern scanning equipment and automated processing, quality control remains essential.
A large-scale digitization project can involve millions of individual pages and thousands of batches of documents. Small errors can become significant problems when they're repeated across that volume.
A quality-control process should account for issues such as:
- Missing or skipped pages
- Duplicate scans
- Incorrect document order
- Cropped, skewed, or unreadable images
- Poor OCR results
- Incorrectly extracted metadata
- Documents assigned to the wrong record
It's also important to establish clear acceptance criteria before production begins. What level of image quality is required? Which metadata fields must be accurate? How will exceptions be handled? What happens when a document can't be processed automatically?
These questions should be answered before the first batch enters production.
Automation can help identify inconsistencies and flag documents that need additional review. Human oversight is still important, particularly when dealing with unusual documents or information that requires additional validation.
The goal is to catch problems as early as possible, rather than discovering them after the physical records have been returned to storage or the project has been completed.
7. Address Security and Compliance Early
Physical records often contain sensitive information. Digitizing them changes how that information is stored, transferred, accessed, and managed.
Security and compliance considerations should be part of the project plan from the beginning.
Depending on your industry and the types of records involved, this may include:
- Access controls: Ensuring employees can only access records they're authorized to view.
- Data privacy: Protecting personal, financial, healthcare, and other sensitive information.
- Audit trails: Maintaining records of document handling, processing, and access.
- Chain of custody: Tracking physical records throughout the digitization process.
- Regulatory requirements: Accounting for applicable requirements such as HIPAA, PCI DSS, and federal information security standards.
- Retention and disposition: Ensuring digitized records remain subject to appropriate retention and destruction policies.
Requirements will vary by organization. A government agency, healthcare provider, and financial institution won't necessarily have the same security obligations. Before selecting a digitization provider, involve your IT security, compliance, and records management teams. Understand how the provider handles physical records, processes information, protects data, and delivers the finished files.
It's much easier to address these requirements during the planning phase than to discover a gap after production is already underway.
8. Decide Where the Digitized Records Will Live
What happens to the documents after they're scanned? This is another question that's easy to overlook.
Ending a digitization project by having a vendor hand you a hard drive packed with disconnected PDFs and saying "Good luck!" is a massive failure. The finished records need to fit into the systems your organization already uses.
This could include:
- Enterprise content management (ECM) systems: Canopy, SharePoint, OpenText, Hyland, etc.
- Cloud storage & data warehouses: AWS, Snowflake, Google Cloud Platform, etc.
- Business applications: Systems such as Salesforce, SAP, ServiceNow, etc.
- Enterprise search & AI applications: Internal search tools, analytics platforms, and retrieval-augmented generation (RAG) workflows.
Before the project begins, establish the file formats, metadata requirements, naming conventions, integration methods, and access controls needed for the destination system.
It's also worth considering whether your organization needs more than document storage. Increasingly, businesses want to extract information from their historical records and make that data available to other applications. That requires thinking about structured data, integration, and downstream use cases from the start.
The objective isn't just to move paper into a digital environment. It's to make the information accessible and useful across the organization.
The Most Successful Digitization Projects Start Before Scanning
Large-scale records digitization is a significant undertaking. It requires more than scanning equipment and a place to store the finished files.
Organizations need to consider the entire process: understanding their records, determining what needs to be preserved, preparing documents, capturing accurate information, validating quality, addressing security, and delivering everything into the right systems.
And when you're dealing with millions of pages, the efficiency of that process matters just as much as the final result.
This is where Ripcord takes a different approach.
Rather than treating digitization as a manual scanning project, Ripcord combines proprietary robotics and AI-powered Intelligent Document Processing (IDP) to automate more of the work involved in turning documents into powerful data.
Here's how that comes together:
- Automated document preparation and scanning. Only Ripcord's proprietary robotic technology uses computer vision sensors to detect and automatically remove staples and other fasteners, and feed pages directly into high-fidelity imaging hardware, eliminating the biggest manual document prep bottleneck in the industry.
- Intelligent data extraction. AI-powered OCR and machine learning help identify document types, extract relevant information, and organize records into structured, searchable data. Human review can be incorporated for documents that require additional attention.
- Connected digital information. Through Canopy, Ripcord's cloud platform, organizations can easily access and manage their digitized information. Data can also be delivered through APIs to support integration with your existing enterprise systems and downstream applications.
The result is a digitization process designed for the realities of enterprise-scale records: high volumes, complex document types, demanding accuracy requirements, and the need to make information useful long after scanning is complete.
Because the real value of digitization isn't measured by how many pages pass through a scanner. It's measured by what your organization can do with that information afterward.
If your organization is evaluating a records digitization project, Ripcord can help you understand the process, identify opportunities for automation, and turn physical record archives into information your teams can actually use.
Request a no-obligation briefing to learn how Ripcord can help you turn your documents into powerful data.

Frequently Asked Questions About Records Digitization
What is large-scale records digitization?
Large-scale records digitization is the process of converting large volumes of physical and digital documents into digital files that can be stored, searched, accessed, and managed electronically. These projects often involve millions of pages and require careful planning around document preparation, scanning, indexing, quality control, and integration with existing systems.
How do you prepare documents for a large-scale digitization project?
Start by understanding what records you have, where they are stored, and how they are organized. Before scanning, remove duplicates and unnecessary materials where appropriate, identify fragile or oversized documents, and establish consistent handling and preparation procedures. You should also determine how documents will be indexed, what information needs to be captured, and how the digital files will be delivered.
How long does it take to digitize millions of records?
The timeline depends on several factors, including the total page volume, document condition, paper sizes, preparation requirements, indexing needs, and quality-control standards. The technology and processes used also make a difference. Establishing a clear scope and workflow before the project begins helps organizations develop more realistic timelines.
What is OCR, and why is it important for digitized records?
Optical character recognition (OCR) converts text within scanned images into machine-readable text. This makes it possible to search for words and information within documents rather than simply viewing each page as an image. OCR can make large digital archives significantly easier to navigate and use.
Why is metadata important in document digitization?
Metadata provides information about a document, such as its type, date, department, record number, or other identifying details. Consistent metadata helps organizations organize records, retrieve the right information, and connect digitized documents to the systems and workflows where they are needed.
How can organizations ensure the quality of digitized documents?
A quality-control process should verify that documents have been captured completely and clearly, pages are in the correct order, and required indexing information is accurate. Organizations should establish quality standards before scanning begins and include checks throughout the project, rather than waiting until the end to identify problems.
What should organizations look for in a large-scale digitization partner?
Look for a partner with experience handling high-volume records, a clear approach to document preparation and quality control, and technology that supports accurate scanning, data extraction, and indexing. It's also important to understand how the provider handles information security, integrates with existing systems, and makes digitized records accessible after the project is complete.